 ENEnglish
 LTLietuviškai
 DEDeutsch
 FRFrançais
 RUРусский
 ESEspañol
 PLPolski
 ITItaliano
 UKУкраїнська
 CSČeština
 PTPortuguês
 JA日本語
 LVLatviešu valoda
 ETEesti
 HUMagyar
 IDBahasa Indonesia
 TRTürkçe
 HIहिन्दी
 ELΕλληνικά
 ARالعربية
 THไทย
 VITiếng Việt
 RORomână
 MSBahasa Melayu
 BNবাংলা
#Crawling
Crawling is how search engine bots discover pages by following links and reading sitemaps. If a page cannot be crawled, it usually cannot rank. Crawling is shaped by robots.txt rules, internal links, server responses and site speed. Most small sites never hit crawl limits, but they often have crawl traps and dead ends. Articles under this tag explain how crawlers move through a website and how to make that path clear.
 1 de out. de 2026 · 8 min de leitura
URL Parameters and SEO: Filters, Tracking and Crawl Waste
URL parameters from filters, sorting and tracking tags create endless duplicate URLs. Learn which ones to index, canonicalise or block, with clear examples.
 30 de set. de 2026 · 8 min de leitura
JavaScript SEO Basics: Can Google See Your Content?
Google can render JavaScript, but not always quickly or completely. Learn how JavaScript affects crawling and indexing, and how to check what Google sees.
 30 de set. de 2026 · 8 min de leitura
Orphan Pages: How to Find Pages With No Internal Links
Orphan pages have no internal links pointing to them, so visitors and search engines rarely find them. Learn how to spot orphan pages and…
 29 de set. de 2026 · 7 min de leitura
HTTP Status Codes for SEO: What 200, 404, 410 and 503 Mean
Learn which HTTP status codes matter for SEO, how Google treats 200, 301, 404, 410, 500 and 503, and how to find pages returning…
 13 de set. de 2026 · 7 min de leitura
Pagination and SEO: How to Handle Page 2, 3 and Beyond
How search engines treat paginated category and blog pages, why page 2 should not canonicalise to page 1, and best practices for infinite scroll…
 3 de set. de 2026 · 8 min de leitura
Crawl Budget Explained: Does It Matter for Your Website?
What crawl budget is, why most small sites do not need to worry about it, the warning signs that it matters, and how to…
 29 de ago. de 2026 · 8 min de leitura
Robots.txt vs Noindex: Which One Should You Use?
Robots.txt controls crawling, noindex controls indexing. Learn the difference, which to use for common page types and why combining them backfires.
 17 de ago. de 2026 · 8 min de leitura
Internal Linking for SEO: A Practical Guide for Small Sites
How internal links help visitors and search engines, how to plan a simple link structure, write good anchor text and fix orphan pages and…
 10 de ago. de 2026 · 8 min de leitura
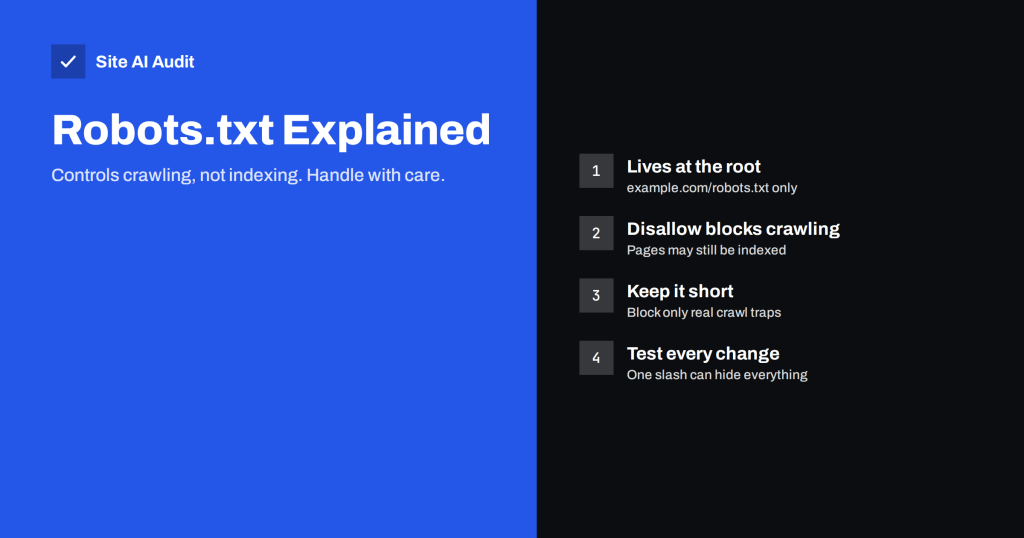
Robots.txt Explained: A Beginner’s Guide With Safe Examples
What robots.txt does and does not do, how its rules work, safe examples for WordPress and shops, and the mistakes that can block a…
 8 de ago. de 2026 · 8 min de leitura
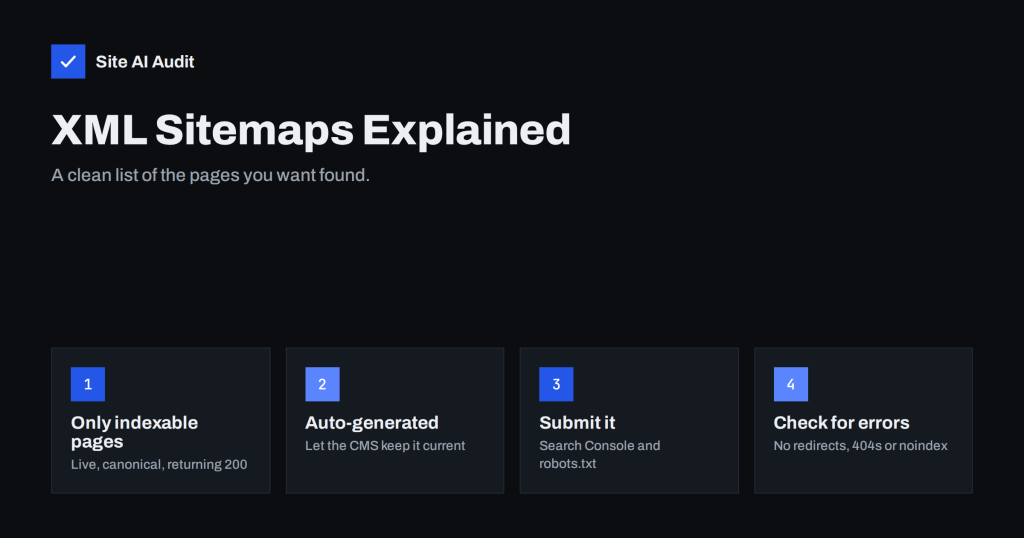
XML Sitemaps Explained: How to Create and Submit One
What an XML sitemap does, which pages belong in it, how to create and submit one to search engines, and how to fix the…